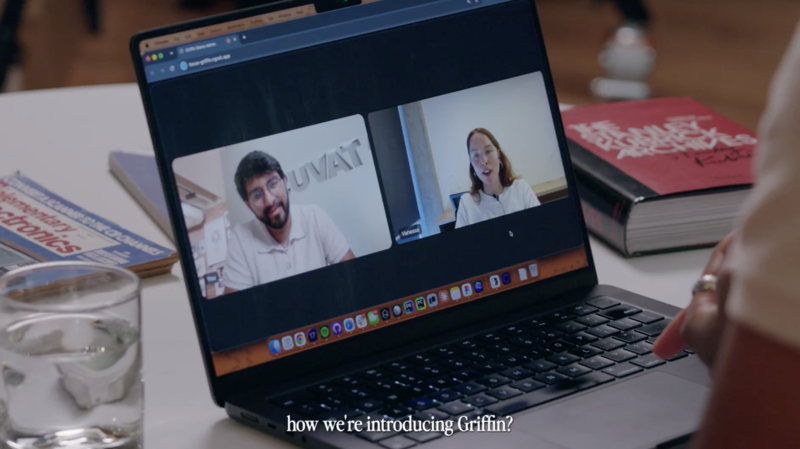
Nearly half of participants who spoke for one minute believed their interlocutor was human, but it was actually an AI. On October 1, US company Tavus announced "Griffin," a conversational model that understands and responds to both audio and video simultaneously.
Introducing Griffin, the first model to pass the video Turing test. 48% of people who talked to it live thought it was a real human. Previous systems have had a pass rate <3%. It is #1 on NVIDIA's benchmark for full-duplex AI video. It’s the first Human Interaction Model (HIM). pic.twitter.com/eb11XbC8Xr — Tavus (@tavus) October 1, 2026
In internal tests, 26 out of 54 participants (48%) who had a one-minute video call with "Griffin-Lite," a research preview of the model, judged the interlocutor to be a real human. The company informed recruited participants from the US and Europe that they would be speaking with another participant during the test.
Instead of waiting for the other party to finish speaking before responding, Griffin is designed to continuously make decisions such as speaking, waiting, and interjecting within intervals of less than one second, all while processing audio and video. It also generates facial expressions, gaze, and gestures in sync with the flow of conversation.
Currently, Griffin-Lite is only available to early testers. Tavus states that conversational models indistinguishable from humans require cautious deployment, and is working on safety measures, including features to indicate that it is an AI. General availability is planned after these issues are addressed.